
Documents API
Every route, field, status and error for sending, reading, updating and erasing documents.
In short
Every route for your documents, with every field, status and error. To learn what to send and what comes out of it, start with Documents.
| To | Call |
|---|---|
| Send or update a document | PUT /agents/{agent_id}/documents/{doc_id} |
| Fetch its state | GET /agents/{agent_id}/documents/{doc_id} |
| List documents | GET /agents/{agent_id}/documents |
| Count documents by state | GET /agents/{agent_id}/documents:count |
| Find documents by the start of their id | POST /agents/{agent_id}/documents/ids:search |
| Find the documents filed beside one | POST /agents/{agent_id}/documents/neighbours:search |
| Resolve a citation | POST /agents/{agent_id}/documents/citations:resolve |
| Read around a passage | POST /agents/{agent_id}/documents/text:window |
| Erase a document | DELETE /agents/{agent_id}/documents/{doc_id} |
Every route belongs to one agent, and none of them creates it. Create it once with POST /agents (see Agents API).
Access control
Reads (GET, POST /citations:resolve, POST /text:window) need agents:read and writes (PUT, DELETE) need agents:write, plus the matching relationship on the agent. There is no separate documents scope. See Access control.
Is it ready?
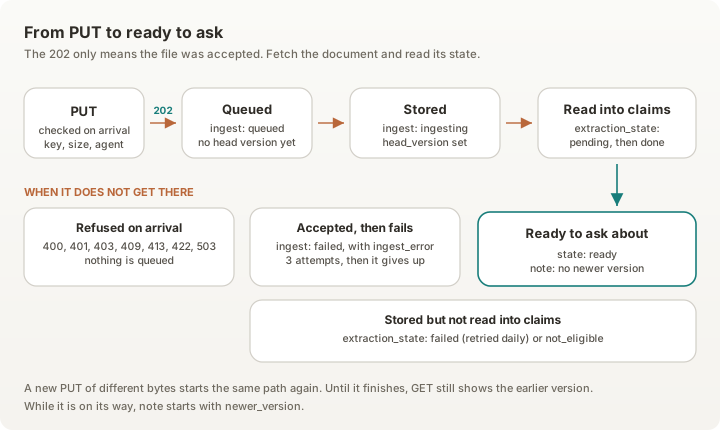
A 202 means the file was accepted. Fetch the document to see how far it has got. It is ready to answer from when state is ready and note doesn't start with newer_version.
state, note and reason are described under What each document carries. The fields below show the same progress in finer detail, for when you need to see which step a document is on.
Prop
Type
| What you see | What it means, and what to do |
|---|---|
ingest: queued, head_version: null | Waiting for a worker. Keep polling. |
ingest: ingesting, head_version: null | A worker has it and is storing it. Keep polling. |
ingest: ingesting, extraction_state: pending | Stored, now being read into claims. Keep polling. |
head_version is your version, extraction_state: done | Ready. The agent can answer from it. ingest is normally ingested here, and stays failed if the claims were read later by the daily retry. |
extraction_state: done with an extraction_reason | Ready, but the text was longer than the agent reads into claims in one pass. The reason gives how much was read out of the text it had to read, for example claims read from the first 256,000 of 412,880 characters. The limit depends on the model doing the reading. The whole text is still stored and can still be cited. |
extraction_state: failed | Stored, but not read into claims, so the agent cannot answer from it yet. A daily pass reads it again, without you sending anything, though a large backlog can take more than one day. spend_limit_reached means your spend limit stopped it. the ingest job ended before claims were read means the work stopped after the text was stored. |
extraction_state: not_eligible | Claim extraction is off for this agent, so the agent cannot answer from it. |
ingest: failed, head_version is your version, extraction_state: failed | Stored, but the work stopped before the claims were read. The daily pass reads it again. |
ingest: failed, head_version: null | Nothing was stored. ingest_error says why, for example a bad X-Document-Type or no text. Fix the cause, then send it again. |
ingest: failed, head_version is an earlier version | Your latest upload was not stored, and the earlier version is still the one in use. ingest_error says why. |
While an update is on its way, state stays ready and note starts with newer_version. Until the new version is stored, GET still shows the previous one as head_version, with its extraction_state still done. If you read the finer fields instead of state, check head_version against the version your PUT returned and extraction_state is done, or you will report a stale document as ready.
How long it takes
Poll every few seconds. Only a limited number of documents are read at once, so a document can wait in queued during a large sync, and a longer document takes longer to read.
A failed attempt is tried again on a later pass. After three attempts ingest shows failed.
Send a document
PUT /agents/{agent_id}/documents/{doc_id} stores one submission and queues it. Required scope: agents:write.
The body is multipart/form-data with two parts: content, the document, and metadata, which must state the channel the document came by. A request of any other content type, or one with no metadata part, is refused with 422 and nothing is queued. The content part can be a file upload or a plain form field with no file name; both are read the same way and take the same size limit.
curl -X PUT \
  -H "Authorization: Bearer <API_KEY>" \
  -H "X-Document-Type: pdf" \
  -F "content=@contract.pdf;type=application/pdf" \
  -F 'metadata={"channel": "document_store"};type=application/json' \
  "https://api.hyperstruck.com/agents/<AGENT_ID>/documents/contracts/marrick-haulage/msa-2026.pdf"
It answers 202 straight away. Nothing has been read yet.
{
  "doc_id": "contracts/marrick-haulage/msa-2026.pdf",
  "version": "afa3e6433fd0d06a7897b0370cc7eace15c4c5846045adb3ee81a8356fbae786",
  "state": "queued",
  "enqueued": true,
  "job_id": "d9504afe-1319-4f8d-a961-2f281d253265"
}
Prop
Type
The response has doc_id, version (the sha256 of the bytes you sent, which is that version's identity), state, enqueued and job_id.
Choose the document key
doc_id is yours. It can contain slashes, such as crm/tallis-joinery/site-visit-2026-09-22, and it is used exactly as sent: never trimmed, never normalized. Two keys that differ only by whitespace are two documents.
A key is refused with 400 when it is empty or only whitespace, is longer than 512 bytes of UTF-8, contains a control character or a backslash, starts with /, has an empty segment, or has a . or .. segment.
Say which account it is about
The metadata part is how a document reaches an account. Declare the account in record_context.concerns whenever you already know it, for example when a Slack channel or a CRM record belongs to one customer. That is the most dependable way to file a document. Send name and kind with scheme and value: with both, an account is created the first time you declare it. Without kind, the document is filed only once the agent knows a company by that name from what it has read.
Without concerns, the document is still stored and read, and its account is worked out from what it carries. That happens only when something was read from the document, so a message too short to read is filed under no account.
| The document carries | Where it is filed |
|---|---|
A relation (in_reply_to, thread, version_of or supersedes) to a document that has an account | Under that document's account. |
An outside participant whose email or domain is known to belong to a company | Under that company. A domain becomes known when a document filed under the company has a participant on it, and either the domain is the company's name as one word (marrickhaulage.com for Marrick Haulage) or the participant's organisation is exactly the company's name. Participants marked is_internal and free mail providers never count. |
A doc_id that contains the name of a company the agent already knows, as whole words (crm/marrick-haulage/site-visit-2026-09-22) | Under that company. |
| None of these | From the organizations its text names. This can pick the wrong one, such as a product the note mentions often in place of the customer, or file the document under no account. A company named once is never enough. |
The first row that applies decides. The last two are weighed together, so a document whose doc_id names one company can also be filed under another that its text names often.
Prop
Type
Unknown keys in metadata are refused with 422. These are the members of record_context:
| Member | Limit | Notes |
|---|---|---|
concerns | 4 | Each has scheme (1 to 100 characters, such as crm:account), value (1 to 200) and optional name and kind (organisation, place or thing; a person is refused). The most dependable way to file a document under an account. |
participants | 24 | Each can carry name, email, role, is_internal, email_authentication and more. role is one of organiser, required, optional, non_participant, from, to, cc, bcc, author, requester, reporter, assignee, watcher, mentioned or unknown. Any other role is refused. |
identifiers | 8 | Stable ids for this document, each a scheme and value. |
relations | 8 | Links to other documents: in_reply_to, references, version_of, supersedes, attachment_of or thread. Each has kind, scheme and value, all required. To name another document by its own doc_id, the scheme is source_ref. |
labels | 4 | Outcomes the source attached, such as a ticket resolution. |
A relation can name a document that has not been sent yet, so send documents in any order.
Send each participant's address as email. The address is kept with the document, returned on the document's own GET, and erased with the document. What is learned from the document uses a keyed pseudonym and the domain in its place, so the same person in two meetings becomes one person. A blind copy (bcc) recipient is never kept.
Say whether a sender passed your mail checks. email_authentication is what your mail system found when it checked the sender's authentication: passed, failed or not_checked. A from participant counts as one of your own people only when is_internal is true and this is passed, because a forged address is how a payment instruction is faked. Leave it out when you have no result, and the sender is read as an outside party.
Send the whole context every time
record_context replaces what you sent for this document last time. A participant you leave out of a corrected invite is removed. Send the complete context on every PUT, never just what changed.
Status codes
A refusal queues nothing. The last two rows are accepted with a 202 and fail later.
| Status | When, and what comes back |
|---|---|
202 | Accepted and queued. The body is the submission, with enqueued: true and a job_id. |
202 (a repeat) | These exact bytes are already waiting or being read for this key. Nothing new is queued: you get the same version and the same job_id as the first PUT, and any new metadata is ignored. |
200 | These exact bytes are already stored as a version of this document. Nothing is queued, and the new metadata only fills what the stored version lacks (see Update a document). That version becomes the current one again. The body has state: "read", enqueued: false and job_id: null. |
400 | The key is not valid, and the message names the rule, for example doc_id must not carry a '.' or '..' path segment, which walks out of the document's own prefix, got 'notes/../x'. |
401 | No key was sent: Missing API key. |
403 | Missing required scope when the key lacks agents:write. Not authorized when it cannot reach that agent, which is also the answer for an agent id that does not exist. |
409 | Another upload of this document changed it while yours was being applied: This document changed while your upload was being applied. Nothing was lost; send it again to make it the current version. Send it again. |
413 | The document is over 25 MiB (26,214,400 bytes). See Size limit. |
422 | No channel stated: a request that is not multipart, has no metadata part, or has metadata with no channel. The message says channel is required and lists every accepted value. Also a multipart request with no content part, or metadata that is otherwise malformed (metadata refused: ..., naming each field and why, never the value you sent). |
500 | Unexpected document error, a fault on our side. Send it again: retrying is safe. |
503 | The document service is unavailable, your tenant's key cannot be read, or participant email addresses cannot be keyed right now. The message names the cause. |
202, then ingest: failed | An X-Document-Type that is not one of the five (ingest_error: 'spreadsheet' is not a valid DocumentType), or an empty body, a blank file or a file with no extractable text (Document contains no text content). |
202, then extraction_state: failed | The document was stored and reading it into claims failed. extraction_reason says why, and a daily pass reads it again. |
Error bodies have the shape {"detail": "..."}.
Retrying a PUT is safe. A retry after a timeout sends the same bytes to the same key, and gets either the first PUT's 202 and job_id back (still in progress) or a 200 (already stored). It never queues the document twice.
Size limit
A document can be up to 25 MiB (26,214,400 bytes): the content part of the multipart body. There is no separate limit on how much text it holds. A larger document is refused with 413 and a detail naming both sizes:
{
  "detail": "this document is 27262976 bytes and the ceiling is 26214400; the ceiling is what the ingest worker can finish inside its timeout, so a larger document is refused here rather than failing three times"
}
A whole request over 26 MiB (27,262,976 bytes, which leaves 1 MiB for multipart overhead and metadata) is refused before it is read, with Request body too large: the limit for this route is 27262976 bytes.
A very long text is still accepted, stored whole and citable. Claims are read from as much of it as the agent can read in one pass, and extraction_reason tells you when that stopped short of the end (see Is it ready?).
Update a document
Send different bytes to the same key and a new version is created and read again. You do not need to delete anything first.
- The new version becomes the current one when it is stored. Until then
GETstill shows the old one. - The old version's
statebecomessuperseded. That is not a failure. It stays listed inversions. - Reading the new version is a new extraction, with the same wait as a first send.
relationisamendson every version sent through this route. There is no way to sendreplaceshere.
The last upload you send wins. If you send version 2 and then version 3 before version 2 has been picked up, version 2 is canceled before it is read and never becomes current; version 3 does. If an older upload happens to finish after a newer one, the newer one still ends up current.
Sending an earlier version's bytes again brings it back. The route answers 200 with state: "read", enqueued: false and job_id: null, nothing is read again, and that version becomes the current one straight away.
Bytes that are already stored are not read again. The metadata sent with them fills a title, a source_url, an occurred_at or a channel the stored version lacks, and never replaces one you declared. A declared title does replace one read off the document's own pages, and a stored occurred_at of +00:00 takes the same moment stated with a real offset. An occurred_at later than the arrival of the earliest stored version of the same text is not filled, and one that is filled lands on that version. A stored channel of unknown counts as lacking one, so sending the same bytes again with the real channel corrects it. The rest of that metadata is ignored. To correct anything else about a stored document, send bytes that differ.
List documents
GET /agents/{agent_id}/documents returns the agent's documents, newest arrival first. Required scope: agents:read. A document sent more than once is listed once, at its newest upload, and an erased document is not listed.
curl -H "Authorization: Bearer <API_KEY>" \
  "https://api.hyperstruck.com/agents/<AGENT_ID>/documents?limit=2"
{
"items": [
{
"doc_id": "slack/C0MARRICK/1791423500.000200",
"title": null,
"author": "Fenn Lacey",
"opening": "Yes, go with Tuesday. The Marrick Haulage cutover moves to Tuesday 20 October…",
"file_name": null,
"state": "ready",
"note": null,
"reason": null,
"occurred_at": "2026-10-09T01:00:00Z",
"arrived_at": "2026-10-12T13:07:33.518642Z",
"document_type": "markdown",
"size_bytes": 134,
"channel": "chat",
"container_name": "#marrick-cutover",
"zone": "Australia/Sydney",
"effects": {"established": 1, "ended": 1, "undecided": 0, "since_replaced": 0, "since_followed": 0, "since_ended": 0},
"is_effects_unavailable": false
},
{
"doc_id": "crm/tallis-joinery/site-visit-2026-09-22",
"title": "Tallis Joinery site visit",
"author": "Fenn Lacey",
"opening": null,
"file_name": "site-visit.md",
"state": "ready",
"note": null,
"reason": null,
"occurred_at": "2026-09-22T09:00:00Z",
"arrived_at": "2026-10-12T13:01:10.204871Z",
"document_type": "markdown",
"size_bytes": 356,
"channel": "meeting",
"container_name": null,
"zone": "UTC",
"effects": {"established": 5, "ended": 0, "undecided": 0, "since_replaced": 0, "since_followed": 0, "since_ended": 0},
"is_effects_unavailable": false
}
],
"next_cursor": "eyJ0cyI6IjIwMjYtMTAtMTJUMTM6MDE6MTAuMjA0ODcxKzAwOjAwIiwi..."
}| Query parameter | What it does |
|---|---|
limit | Documents per page, 1 to 100. Defaults to 25. A value outside the range is a 422. |
cursor | The next_cursor of the page before. next_cursor is null on the last page. A cursor that cannot be read is a 400. |
state | Keep only documents in this state: queued, ingesting, ready, paused or failed. Repeat it to admit several (?state=failed&state=paused). Any other value is a 422. |
What each document carries
Prop
Type
Name a row by what it has. Show title when there is one. Without a title, show author and opening together (Fenn Lacey: Yes, go with Tuesday…), then fall back to file_name, and to doc_id for a document that is still on its way. A chat message or an email rarely has a title, so a list of them reads by who wrote each one and how it starts.
author comes from the first participant who originated the document: an organiser, from, author, requester or reporter. So an email's sender sets it.
The list, the id search, the search for documents filed beside one, and the single-document GET all answer with Cache-Control: no-store, because an opening is document text.
Protected values are withheld. Every route that returns a document's text replaces a protected value, such as a bank account number, with "Ends 8765" wherever it would show: an opening, a quote, a passage. Add ?reveal=true to see them; only a caller holding claims:curate who may also change the agent may ask, and anyone else gets 403 curate_required. More on withheld values.
Count documents by state
GET /agents/{agent_id}/documents:count returns how many documents the agent holds in each state. The five states sum to total.
{
  "total": 3,
  "queued": 0,
  "ingesting": 0,
  "ready": 3,
  "paused": 0,
  "failed": 0,
  "completed_last_10_minutes": 1,
  "last_arrived_at": "2026-10-12T13:31:03.607308Z"
}
completed_last_10_minutes is the number of uploads that finished in the last ten minutes, which tells you how fast a large sync is being read.
Find documents by the start of their id
POST /agents/{agent_id}/documents/ids:search returns the documents whose id starts with doc_id_prefix, in id order, each in the same shape as a list item. The match is exact and case-sensitive, and no character is a wildcard. The prefix goes in the body, so it stays out of the URL.
curl -X POST "https://api.hyperstruck.com/agents/<AGENT_ID>/documents/ids:search" \
  -H "Authorization: Bearer <API_KEY>" \
  -H "Content-Type: application/json" \
  -d '{"doc_id_prefix": "slack/C0MARRICK/", "limit": 25, "states": ["failed", "paused"]}'
limit defaults to 25, and a value above 100 is treated as 100. states is optional. A search has no next page: has_more: true means more documents matched than limit allowed, so send more of the id, or a state, to narrow it.
Find the documents filed beside one
POST /agents/{agent_id}/documents/neighbours:search returns the documents filed in the same container as doc_id (a chat channel, an email thread or a declared account) just before and just after it, by the time each declared. Required scope: agents:read.
curl -X POST "https://api.hyperstruck.com/agents/<AGENT_ID>/documents/neighbours:search" \
  -H "Authorization: Bearer <API_KEY>" \
  -H "Content-Type: application/json" \
  -d '{"doc_id": "slack/C0MARRICK/1791423500.000200", "span": 2}'
The response has container (the container the documents share, or null), and before and after, each a list of up to span documents (1 to 5, default 1), nearest first, in the same shape as a list item. Each is shown by its opening words, titled or not. Only documents whose text is kept and that have been read are named. A document that declares only a thread is filed under that thread.
Fetch a document
GET /agents/{agent_id}/documents/{doc_id} returns the document's state and every stored version. Required scope: agents:read. A key that was never sent and has nothing queued is 404, with {"detail": "no document '...' has been written under this agent, and nothing is queued for it either"}.
curl -H "Authorization: Bearer <API_KEY>" \
  "https://api.hyperstruck.com/agents/<AGENT_ID>/documents/crm/tallis-joinery/site-visit-2026-09-22"
{
"doc_id": "crm/tallis-joinery/site-visit-2026-09-22",
"head_version": "3fa30a2f32c53962246fc255da1803d26ff0c362903f195b58018c2eafaaed0c",
"ingest": "ingested",
"ingest_error": null,
"version_state": "read",
"versions": [
{
"version": "3fa30a2f32c53962246fc255da1803d26ff0c362903f195b58018c2eafaaed0c",
"state": "read",
"document_type": "markdown",
"size_bytes": 356,
"relation": "amends",
"previous_version": null,
"retention_class": "normalised_only",
"created_at": "2026-10-30T17:34:56.086339+00:00"
}
],
"extraction_state": "done",
"extraction_reason": null,
"state": "ready",
"note": null,
"reason": null,
"title": "Tallis Joinery site visit",
"author": "Fenn Lacey",
"opening": null,
"file_name": "site-visit.md",
"effects": {"established": 5, "ended": 0, "undecided": 0, "since_replaced": 0, "since_followed": 0, "since_ended": 0},
"is_effects_unavailable": false,
"text_sha256": "a209d5f66e9cfbf0dd5daab3ab05cc04f2ebd440ed2e8d8c22df852c1ef17229",
"segmenter_version": "2",
"occurred_at": "2026-09-22T09:00:00Z",
"channel": "meeting",
"container_name": null,
"zone": "UTC",
"record_context": {
"record_kind": null,
"occurred_at": null,
"containers": [
{"scheme": "crm:account", "value": "tallis-joinery", "name": "Tallis Joinery", "kind": "organisation"}
],
"participants": [
{"name": "Hugh Sallis", "role": "required", "organisation": null, "address": "hugh@tallisjoinery.example"},
{"name": "Fenn Lacey", "role": "organiser", "organisation": null, "address": "fenn@pellrudd.example"}
],
"identifiers": [],
"relations": [],
"labels": []
}
}Prop
Type
Add ?job_id= with the job_id a PUT returned, and ingest and ingest_error describe that upload's own job, so an upload that a newer one canceled shows why.
GET returns state only. It never returns the document's text. To read the text, start from a citation (see Read around a passage).
Resolve a citation
An answer quotes a passage and gives it a citation. POST /agents/{agent_id}/documents/citations:resolve turns that citation back into the passage. Required scope: agents:read.
Take the citation from a claim item's cite.passage, from Claims search or the Claims API, and send it unchanged. This route never returns a citation, so you cannot build one from here.
curl -X POST \
  -H "Authorization: Bearer <API_KEY>" \
  -H "Content-Type: application/json" \
  -d '{
    "citation": {
      "doc_id": "crm/tallis-joinery/site-visit-2026-09-22",
      "text_sha256": "a209d5f66e9cfbf0dd5daab3ab05cc04f2ebd440ed2e8d8c22df852c1ef17229",
      "segmenter_version": "2",
      "unit_index": 4,
      "start": 209,
      "end": 283
    }
  }' \
  "https://api.hyperstruck.com/agents/<AGENT_ID>/documents/citations:resolve"
{
"outcome": "resolved",
"citation": { "doc_id": "crm/tallis-joinery/site-visit-2026-09-22", "text_sha256": "a209d5f66e9cfbf0dd5daab3ab05cc04f2ebd440ed2e8d8c22df852c1ef17229", "segmenter_version": "2", "unit_index": 4, "start": 209, "end": 283 },
"quote": "Fenn Lacey agreed to send a Ludlow rollout plan to Hugh by 6 October 2026.",
"retained_quote": null,
"retained_end_char": null,
"source_retained_end_char": null,
"digest": "5af54f9368d2b37f47795b6e49ab8e798bbed8757b744e15f6cc94c393c815a5",
"doc_id": null,
"reason": null
}All six members are required. text_sha256 is the hash of the document's text, not the version a PUT returned. unit_index numbers the passage, and start and end are character positions in the document's text.
outcome | Meaning |
|---|---|
resolved | The passage is in quote. |
erased | The document was erased. doc_id names it. |
missing | Nothing matched. reason says why, for example offsets [209, 9999) fall outside unit 4, which spans [209, 283) or no unit of that identity is stored for this agent. |
truncated | Part of the passage is held (retained_quote, retained_end_char). Documents sent through this route are stored whole, so you should not see it here. |
When a protected value is withheld from the quote, retained_end_char counts the returned text and source_retained_end_char the stored text.
Show erased and missing differently. One means the document was deleted, the other means nothing matched. A document outside the spaces your key can read also answers missing, worded exactly as one that was never sent.
If your tenant has never sent a document, this route answers 409 (this tenant has no active document key binding: ...). Send a document first.
Read around a passage
A quote is often too short to judge on its own. POST /agents/{agent_id}/documents/text:window returns the passages either side of a cited one, so you can show the reader the surrounding text. Required scope: agents:read.
Send the first four members of the citation, and how many passages you want before and after it:
curl -X POST \
  -H "Authorization: Bearer <API_KEY>" \
  -H "Content-Type: application/json" \
  -d '{
    "doc_id": "crm/tallis-joinery/site-visit-2026-09-22",
    "text_sha256": "a209d5f66e9cfbf0dd5daab3ab05cc04f2ebd440ed2e8d8c22df852c1ef17229",
    "segmenter_version": "2",
    "unit_index": 4,
    "before": 1,
    "after": 1
  }' \
  "https://api.hyperstruck.com/agents/<AGENT_ID>/documents/text:window"
{
"outcome": "window",
"units": [
{
"unit_index": 3,
"start_char": 130,
"end_char": 207,
"text": "Hugh asked for the Ludlow workshop to go live before the January stock count.",
"source_end_char": null,
"withheld": [],
"heading_path": ["Tallis Joinery site visit", "Rollout"],
"speaker": null,
"is_truncated": false
},
{
"unit_index": 4,
"start_char": 209,
"end_char": 283,
"text": "Fenn Lacey agreed to send a Ludlow rollout plan to Hugh by 6 October 2026.",
"source_end_char": null,
"withheld": [],
"heading_path": ["Tallis Joinery site visit", "Rollout"],
"speaker": null,
"is_truncated": false
},
{
"unit_index": 5,
"start_char": 285,
"end_char": 298,
"text": "## Next steps",
"source_end_char": null,
"withheld": [],
"heading_path": ["Tallis Joinery site visit", "Next steps"],
"speaker": null,
"is_truncated": false
}
],
"has_before": true,
"has_after": true,
"unit_count": 7,
"version_created_at": "2026-10-30T17:37:19.672434Z",
"is_head": true,
"head_version_created_at": null
}beforeandafterdefault to 3. Any value above 25 is treated as 25.has_beforeandhas_aftersay whether more text lies beyond the window, so you can ask again from the first or lastunit_indexyou got back.is_headisfalsewhen the citation points at an earlier version of the document.head_version_created_atthen says when the current version arrived.- When a protected value is withheld from a passage,
end_charcounts the text you receive, andsource_end_charcounts the stored text that citations point into. Each entry inwithheld(start,end,shown_start,shown_end) maps one withheld span from the stored text onto the returned text. outcomeiswindow,erased(the document was erased),missing(no such passage, or a document outside your spaces) orunreadable.unreadablecomes with a503and is a fault on our side, never a statement about the document.- A tenant that has never sent a document gets the same
409ascitations:resolve.
Erase a document
DELETE /agents/{agent_id}/documents/{doc_id} removes the document and what was read from it. Required scope: agents:write. It answers 200 with a receipt.
{
  "doc_id": "ops/copenhagen-handover.md",
  "versions": ["70daf6dd21eeba580389c3ad3bd2251d7327c8adedcaee93e056b54e0daf1efd"],
  "is_complete": true,
  "scopes": [
    {
      "scope": "original_bytes",
      "disposition": "purged",
      "technique": "cryptographic-erase: the wrapped data key is destroyed, then the blob is deleted",
      "count": 1,
      "verified": true,
      "reason": null
    },
    {
      "scope": "claims",
      "disposition": "deleted",
      "technique": "delete of every claim whose only source was this note; claims with other sources keep them",
      "count": 1,
      "verified": null,
      "reason": "a claim's statement is stored unencrypted, so the claims resting on this note alone could not be purged by a key"
    }
  ],
  "cancelled_jobs": 0,
  "erasure_id": "09a594d5-45f0-4261-9ab4-092443eac10a",
  "completed_at": "2026-09-30T19:23:09.334126Z"
}
The real receipt lists every scope. Two are shown.
| Scope | What it covers |
|---|---|
original_bytes, text_units | The file you sent and its stored text. |
vector_points, graph_nodes | The search and link entries built from the text. |
claims, claim_citations | Claims that rested only on this document are deleted. Claims another document also supports stay, and lose only this document's citations. |
record_context, note_record_rows | The title, participants and links you declared. |
stored_answers, standing_answers | Stored answers that quote, read or cover the document. |
harvested_obligations | Obligations read from the document. |
learnings, learning_citations | Learnings distilled from the document. Those only it supported are deleted, and those with other sources stay without it. not_tracked or deleted_incomplete means the erasure could not find them all, so a zero is never reported for learnings it could not have found. |
disposition is purged when the copy was encrypted and its key was destroyed, and deleted when the copy was removed but was never encrypted, so it is only as gone as the delete. The search entries, graph entries, claims, stored answers, declared metadata and obligations are in the second group.
is_completeistrueonce the erasure has finished and every place that can hold the document has answered.completed_atis set at the same time.- Repeating the
DELETEis safe. It returns the same receipt with the sameerasure_id. A document erased, sent again and erased again is two erasures. - Erasing a key under which nothing was ever stored (never sent, or an upload that failed before it was stored) still answers
200, with an emptyversionslist, zero counts andis_complete: true, because there was nothing to erase. - A tenant that has never sent any document gets
409fromDELETE, with the same message as Resolve a citation. - Queued work is canceled.
cancelled_jobscounts waiting ingests, and theiringest_errorbecomescancelled by an erasure of this document. - After an erasure,
GETanswers404, the same as for a key that was never sent, and the document leaves the list and the counts at once. A citation into the document resolves aserased.
Keep the receipt. It is the record that the erasure happened.
What you cannot do
- Read a document's text without a citation.
text:windowreads from a cited passage outward. No route takes just adoc_idand returns its text. - Download the original. The original file is deleted once its text is stored.
- Mark an update as a replacement. Every update is an
amends. - Send a document over 25 MiB.
How documents relate to answers and distill
Your agents answer from the claims read from each document, open obligations among them, and Claims search returns the claims nearest a question. Reading a document draws on your tenant's learning spend. No learnings come out of it.
Distill is a different route that turns a corpus into learnings. For tenants where it is switched on, each item /distill reads is also stored as a document of the same agent, and those documents then appear under this API.
Documents
What to send and what comes out, explained from the start.
Send messages and large syncs
Chat, email and a first big upload.
Claims search
Ask a question and get back the nearest claims, cited to the documents you sent.
Distill
Turn a corpus into learnings and claims.
Claims API
Review and govern what your agents believe.
Access control
Scopes and relationships for these routes.